FME Transformers: 2026.3
 Categories and Related Transformers
Related Transformers
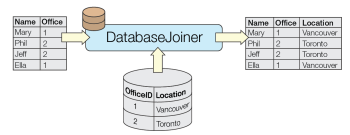
DatabaseJoiner
FeatureJoiner
InlineQuerier
ListBasedFeatureMerger
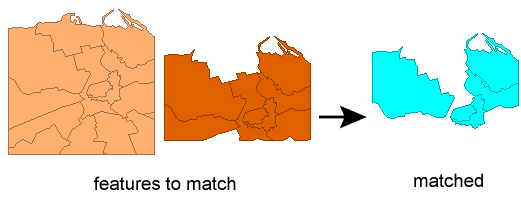
Matcher
SQLCreator
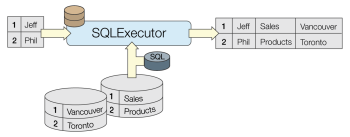
SQLExecutor
Merges the attributes and/or geometries of one set of features onto another set of features, based on matching key attribute values and expressions.
Typical Uses
- Combining attributes and/or geometries from two different streams of features, based on a common key attribute value or expression.
How does it work?
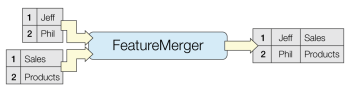
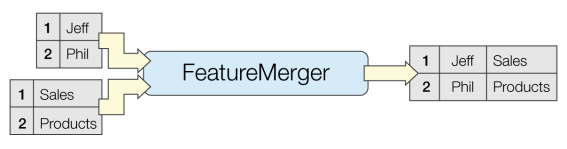
The FeatureMerger receives two streams of features via its input ports.
Requestor: Requestors are the features that will receive new attributes and/or geometries.
Supplier: Suppliers provide attributes and/or geometries to be merged onto the Requestors.
Matches between Requestor and Supplier are identified according to the Join On configuration in the parameters dialog. The Join conditions can be simple or complex, using attribute values, constants, functions, or a combination of any of these in expression form. Multiple join conditions can be defined (features must meet all conditions to match).
When a Requestor finds a matching Supplier, the attributes and/or geometries from the Supplier are merged onto the Requestor.
- If the Requestor already has an attribute that the Supplier also has, the Requestor's original value for that attribute can be preserved or overridden.
- A single Supplier may be used by many Requestors.
- Many Suppliers can be merged onto a single Requestor.
- When attribute names conflict, you can choose whether Requestor or Supplier attribute values are maintained by using the Conflict Resolution parameter, and whether null values follow the same behavior by using the Null Value Handling parameter.
Requestor features match Supplier features when every pair of keys (which support expressions) specified in the Join On table has the same value for both the Requestor and Supplier features.
Examples
Example: Merging attributes and geometry to CSV data
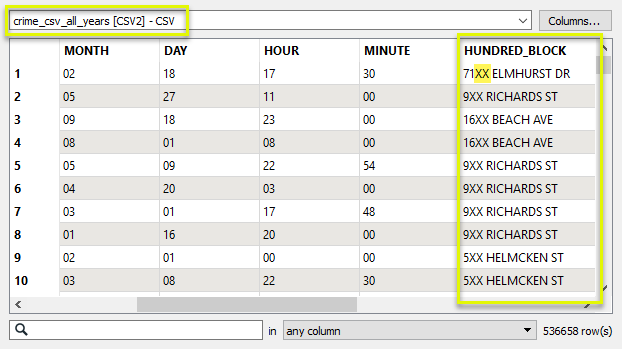
In this example, we have two datasets - a CSV text file of historical crime reports, and a shapefile of public streets. Both of the datasets have one piece of information in common, that is an address in the form of “hundred” block.
The FeatureJoiner would likely be more effective to do a simple attribute value join, however, the format of the address is slightly different in each dataset. The CSV data uses the string “XX” in place of zeroes in the address:
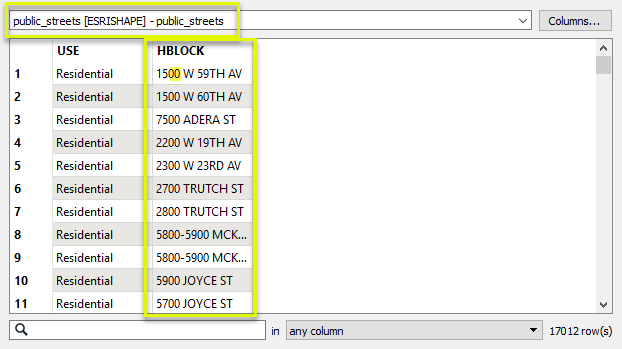
And the street data has the more conventional form, with zeroes:
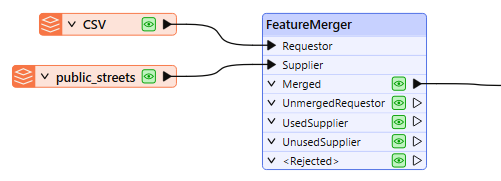
Our goal is to merge the street geometry onto the crime data - producing one output feature for each crime record. And so, The CSV data is routed into the Requestor input port, and the streets are routed into the Supplier port.
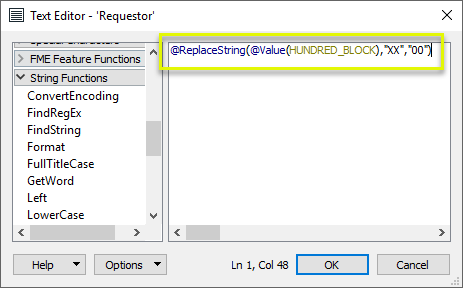
In the parameters dialog, we need to create a Join On pair of Requestor and Supplier values. As the format of the addresses is not identical, we will adjust one, constructing a key. With the assistance of the Text Editor, we create an expression that will replace the “XX” of the address with “00”, and so match the format of the street (Supplier) data.
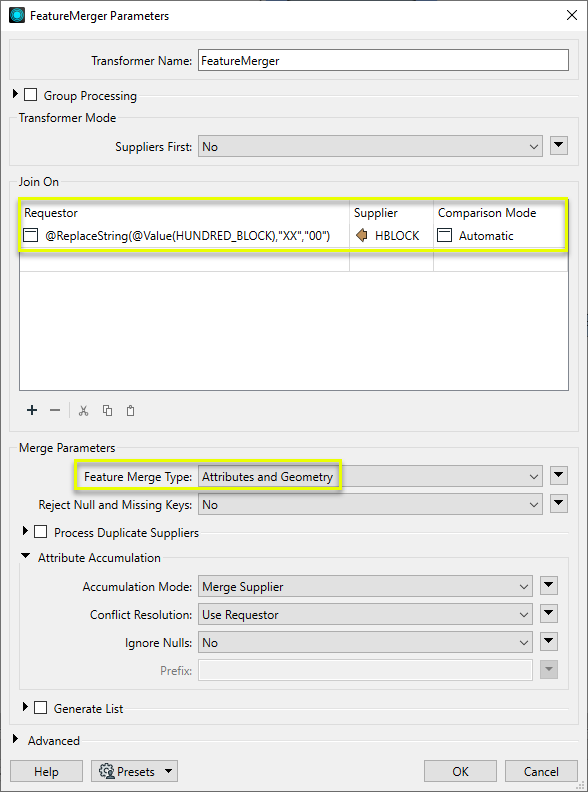
The other half of the pairing is the attribute value HBLOCK from the street data.
Merge Scope is set to Attributes and Geometries. The default values for Attribute Accumulation (Merge Supplier) will provide the correct results.
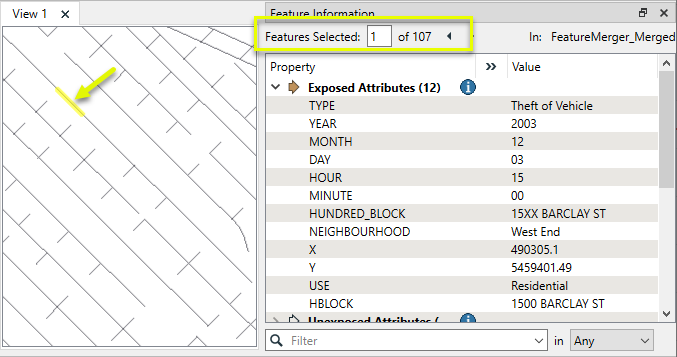
The Merged output contains crime records, now with geometry for the street and associated street attributes. Note that the address format was not actually changed by the constructed expression - it was just used for matching evaluation. In this location, 107 crime records were found. Each one now has (identical) geometry.
To see this example reversed - attaching all crime records to a single street - see the next example.
Example: Many-to-one merging to create a list attribute
In this example, we reverse the scenario in the above example. We want to merge all the historical crime records onto the street data, producing one record per street line segment (block), with a list attribute containing the crime data.
In this case, the streets are the Requestor features, and the crime data is the Supplier.
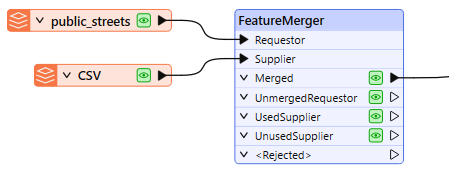
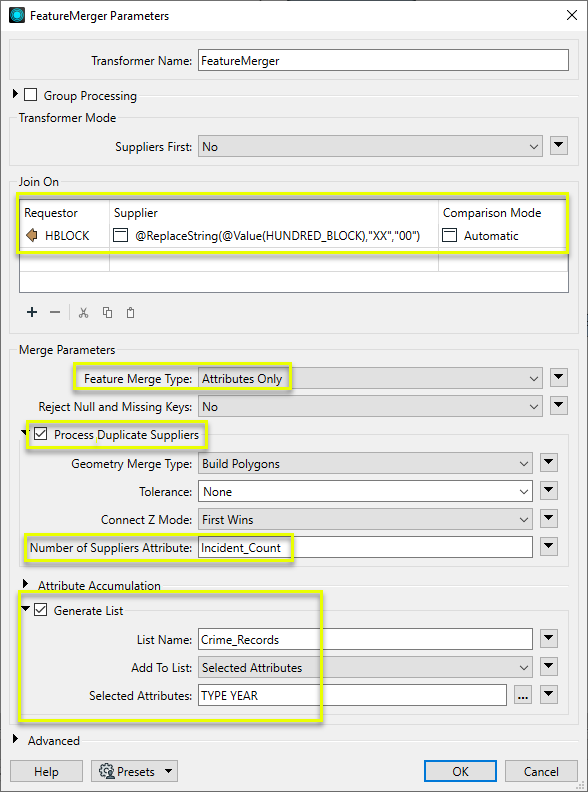
In the parameters dialog, we again create a Join On pair, using an expression to match the two (slightly different) hundred block formats. The Merge Scope is Attributes, as the Requestors (streets) already have the desired geometry.
Process Duplicate Suppliers is enabled. Without this, the first match would be processed and the remainder discarded. A count of how many Suppliers (crimes) matched will be kept in the Output Attribute for Supplier Count, named Incident_Count.
Generate List is enabled, and given the List Name of Crime_Records. We will add only Selected Attributes to the List, and choose TYPE and YEAR.
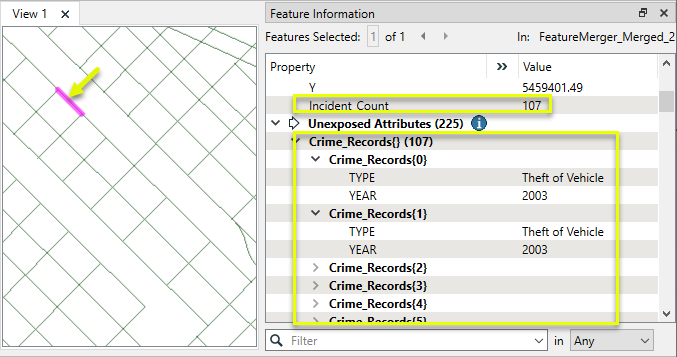
The Merged output features now have a list attribute, containing all matching records from the CSV. Note the Incident_Count attribute.
Usage Notes
- For simple joins, the FeatureJoiner may provide better performance than the FeatureMerger. However, the FeatureJoiner only accepts attribute values as keys and not constructed expressions, and does not support list attributes. Additionally, the FeatureMerger is able to (optionally) restrict output to one feature in the case of multiple matching Suppliers, whereas the FeatureJoiner will create multiple features for all matches.
- For complex joins using SQL syntax, or more than two input feature streams, consider using the InlineQuerier.
- Where multiple FeatureMergers are required, consider using the InlineQuerier instead.
- If all the data to be queried already exists in a SQL-capable data source, it will be more efficient to use the SQLCreator or SQLExecutor, which allows the queries and filtering of the data to be executed directly by the database before it enters the FME environment.
- To perform a join between features already in the workspace and data residing in an external database, consider the DatabaseJoiner.
- To perform a join where the Requestor key is a list attribute, consider using the ListBasedFeatureMerger.
- To join features on matching geometry, consider the Matcher. The FeatureMerger does not accept geometry as a key.
- To join all Suppliers to all Requestors when there is no common join value, setting Join On > Requestor and Join On > Supplier to the same constant value (for example,
1and1) will merge all to all. Enable Generate List to store multiple matches per feature.
Choosing a Feature Joining Method
Many transformers can perform data joining based on matching attributes, expressions and/or geometries. When choosing one for a specific joining task, considerations include the complexity of the join, data format, indexing, conflict handling, and desired results. Some transformers use SQL syntax, and some access external databases directly. They may or may not support list attribute reading and creation.
Generally, choosing the one that is most specific to the task you need to accomplish will provide the optimal performance results. If there is more than one way to do it (which is frequently the case), time spent on performance testing alternate methods may be worthwhile. Performance may vary greatly depending on the existence of key indexes when reading external tables (as opposed to features already in the workspace).
Joining Transformers Comparison
|
Transformer |
Match By |
Uses SQL Statements |
Can Create List |
Input Type |
Notable |
Description |
|---|---|---|---|---|---|---|
| FeatureJoiner | Attributes | No | No | Features |
|
Joins features by combining the attributes and/or geometry of features based on common key attribute values. Performs Left, Inner, and Full joins. |
| FeatureMerger | Attributes | No | Yes | Features |
|
Merges the attributes and/or geometries of one set of features onto another set of features, based on matching key attribute values and expressions.
|
| ListBasedFeatureMerger | List Attribute to Single Attribute | No | Yes | Features |
|
Merges the attributes and/or geometries of one set of features onto another set of features, based on matching list attribute values with key attribute values and expressions. |
| InlineQuerier | SQL query | Yes | No | Features |
|
Creates SQLite database tables from incoming features, executes SQL queries against them, and outputs the results as features. |
|
SQL or Cypher query |
Yes |
No |
External DB |
|
Executes queries against a database, producing query results and/or schema. |
|
| SQLCreator | SQL query | Yes | No | External DB |
|
Generates FME features and/or schemas from the results of a SQL query executed against a database. One FME feature is created for each row of the results of the SQL query.
|
| SQLExecutor | SQL query | Yes | No | External DB |
|
Executes SQL queries against a database.
|
| DatabaseJoiner | Attributes | No | Yes | External DB and Features |
|
Joins attributes from an external table to features already in a workspace, based on a common key or keys.
|
| Matcher | Geometry and/or Attributes | No | Yes | Features |
|
Detects features that are matches of each other. Features are declared to match when they have matching geometry, matching attribute values, or both. A list of attributes which must differ between the features may also be specified.
|
Working with Multiple Geometries
Some formats, such as PostGIS, Oracle Spatial, and Microsoft SQL Server, support multiple geometries on a feature.
They must have unique names, and they have their own coordinate systems and a separate row in the Geometry Definition table.
Multiple geometries are a different concept from aggregates and multis such as MultiPoint.
Multiple Geometries Transformers
|
Transformer |
Use this to... |
|---|---|
|
Add a copy of a feature’s geometry onto itself, either creating or adding to multiple geometry. The copy can then be further processed. |
|
|
Create multiple geometries by merging features based on attribute values and expressions. See Geometry Merge Type > Preserve Distinct Geometries. |
|
|
Create multiple geometries by joining features on attribute values, using left, inner, or full joins. See Geometry Handling > Keep Both (Preserve Distinct Geometries). |
|
|
Assign names to geometries. |
|
|
Put all geometry names into an attribute or list attribute. |
|
|
Make a name available for geometry selection when it is not yet available to downstream transformers. |
|
|
Identify and route features that have multiple geometries. |
|
|
Remove specific geometries by name, or all geometries. Useful for going from multiple geometries to single. |
|
|
Place specific or all geometries into an attribute as a blob. May be useful when paired with the GeometryReplacer for performing transformations on geometry with transformers that do not have geometry selection. |
|
|
Restore geometry from an attribute blob value. |
Transformers with Geometry Selection
These transformers can operate on selected geometries.
Configuration
Input Ports
Requestor
Features that will receive new attributes and/or geometries from the features connected to the Supplier port.
Supplier
The source of new attributes and/or geometries for features that enter through the Requestor port.
Note that by setting Process Duplicate Suppliers to Yes, more than one Supplier may be merged to each Requestor. These Suppliers potentially could come from different sources (such as different database tables).
Output Ports
Merged
Requestors that match a Supplier (or possible multiple Suppliers, if Process Duplicate Suppliers is set to Yes).
UnmergedRequestor
Requestors that do not match any Suppliers. If a Join On key is null or missing on a Requestor feature, that feature is output onto this port.
UsedSupplier
Suppliers that are found by at least one Requestor.
Note A Supplier may still be output through this port even though none of its attributes were merged. This can occur because all of the attributes were already present in the Requestor or were provided by earlier Suppliers.
UnusedSupplier
Suppliers that do not match any Requestors. If a Join On key is null or missing on a Supplier feature, that feature is output onto this port.
<Rejected>
If Process Duplicate Suppliers is No, then duplicate Suppliers will be rejected. If Null and Missing Keys is Reject, then keyless features will be rejected.
Rejected Feature Handling: can be set to either terminate the translation or continue running when it encounters a rejected feature. This setting is available both as a default FME option and as a workspace parameter.
Parameters
Group Processing
|
Group By |
The input features may be partitioned by the Group By parameter. If you choose any Group By attributes, then references between features will only be resolved if they share a common value for the selected attributes. If you do not choose any Group By attributes, all features are processed together. If you have more than one Reader, a typical use is to group by reader_id to ensure that references are resolved within the correct set of features. |
||||
|
Complete Groups |
Select the point in processing at which groups are processed:
Considerations for Using Group By
There are two typical reasons for using When Group Changes (Advanced) . The first is incoming data that is intended to be processed in groups (and is already so ordered). In this case, the structure dictates Group By usage - not performance considerations. The second possible reason is potential performance gains. Performance gains are most likely when the data is already sorted (or read using a SQL ORDER BY statement) since less work is required of FME. If the data needs ordering, it can be sorted in the workspace (though the added processing overhead may negate any gains). Sorting becomes more difficult according to the number of data streams. Multiple streams of data could be almost impossible to sort into the correct order, since all features matching a Group By value need to arrive before any features (of any feature type or dataset) belonging to the next group. In this case, using Group By with When All Features Received may be the equivalent and simpler approach. Note Multiple feature types and features from multiple datasets will not generally naturally occur in the correct order.
As with many scenarios, testing different approaches in your workspace with your data is the only definitive way to identify performance gains. |
Join On
This table specifies the keys to match in order to join Requestors and Suppliers.
|
Requestor Keys |
Specify an expression from the Requestor feature to match with the Supplier feature expression. An expression can be a constant, attribute value, function or mixture. Leading and trailing space characters are trimmed from the evaluated expressions. Matches are made when the trimmed values of all the Requestor expressions equal the trimmed values of their corresponding Supplier expressions. |
|
Supplier Keys |
Specify an expression from the Supplier feature to match with the Requestor feature expression. An expression can be a constant, attribute value, function or mixture. Leading and trailing space characters are trimmed from the evaluated expressions. Matches are made when the trimmed values of all the Requestor expressions equal the trimmed values of their corresponding Supplier expressions. Generally, the Suppliers will have expressions defined that result in a unique match with a Requestor, and any duplicate Suppliers are ignored by the transformer. However, if the Process Duplicate Suppliers parameter is set to Yes, then all Suppliers whose expressions match their corresponding Requestor expressions will be combined onto that Requestor. |
|
Comparison Mode |
The Comparison Mode column specifies how to perform the comparison between Requestor and Supplier attribute values. If Automatic or Numeric is specified, an attempt will be made to convert attribute values to numbers before comparing them. |
Input Handling
|
Assumed Input Order |
Select a method of handling input features:
Note If using Suppliers First, it is the user’s responsibility to make sure all the Suppliers arrive before the Requestors. The transformer will stop accepting Suppliers once it receives its first Requestor.
|
|
Merge Scope |
Select what to merge onto the completed feature:
|
Process Duplicate Suppliers
If more than one Supplier is found for a given Requestor, and Process Duplicate Suppliers is not enabled, then every Supplier after the first is output via the <Rejected> port and only the first of the Suppliers will be matched with a Requestor.
If Process Duplicate Suppliers is enabled, duplicate Suppliers are all matched with the corresponding Requestor. Attributes are merged based on the Attribute Accumulation mode, and optionally output as a list attribute of the Requestor, using the specified List Name. The Supplier geometry is merged using the specified Supplier Geometry Assembly.
|
Supplier Geometry Assembly |
When Merge Scope is Geometries or Attributes and Geometries, select a method of handling multiple Supplier geometries:
|
||||||||||||||||||
|
Tolerance |
The minimum distance between geometries in 2D before they are considered equal, in ground units. If the tolerance is None, the geometries must be exactly identical to be considered equal. If the tolerance is Automatic, a tolerance will be automatically computed based on the location of the input geometries. Additionally, a custom tolerance may be used. |
||||||||||||||||||
|
Connect Z Mode |
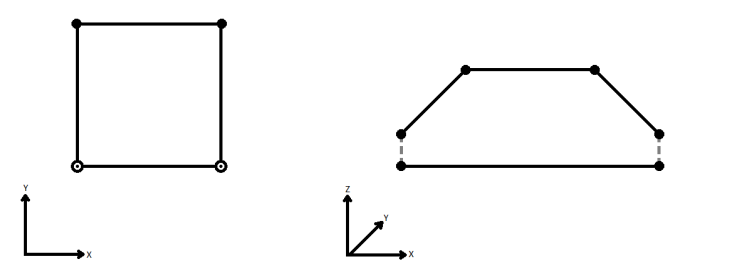
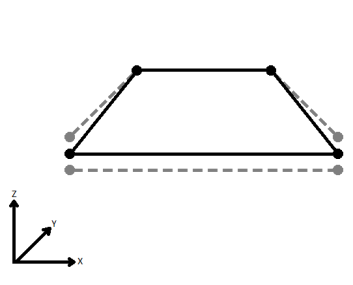
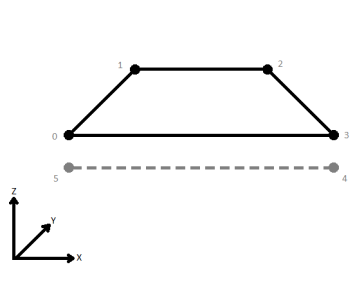
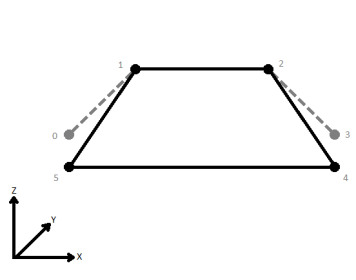
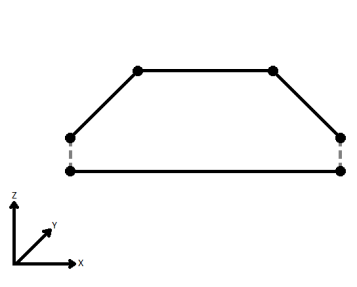
If applicable, select a method for handling z values. Connect Z Mode
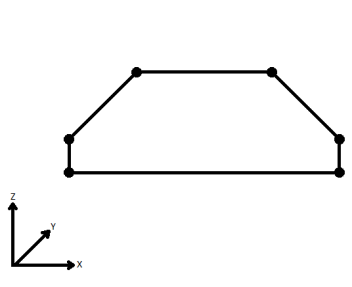
When viewed in 2D (ignoring Z), a path (which may define the border of a polygon) may appear to be closed as shown in the left figure below. This same path, when viewed in 3D, may appear to be open as shown in the right figure below.
To specify how (and if) paths should be closed in 3D, select one of the listed modes.
|
||||||||||||||||||
|
Output Attribute for Supplier Count |
Name the attribute to contain a count of the number of Suppliers matched a Requestor. |
||||||||||||||||||
|
Generate List |
When enabled, duplicate Suppliers will have their attributes added to the specified list on the Requestor. Note List attributes are not accessible from the output schema in FME Workbench until they are exposed with an AttributeExposer or processed with a transformer that operates on them, such as a ListExploder or ListConcatenator.
|
 Attribute Accumulation
When Merge Scope is Attributes or Attributes and Geometries, attributes are accumulated.
If attributes on the Supplier and Requestor feature share the same name, but are not geometry attributes that start with fme_, then they are deemed conflicted.
|
Accumulation Mode |
Select a method for merging attributes:
|
|
Conflict Resolution |
Select a method of resolving same-name collisions:
|
|
Null Value Handling |
Select a method for handling null attributes:
Note Null and other attribute values are always more dominant than missing attribute values. That is, whenever an attribute value is merged with a missing attribute value, the attribute value shall prevail, regardless of the Null Value Handlingand Conflict Resolution settings.
|
|
Prefix |
When Accumulation Mode is Prefix Supplier, provide a prefix to be applied to the Supplier attributes. When there are multiple Supplier features for a Requestor feature, multiple Supplier attribute values are merged into the same prefixed attribute. When multiple Supplier features have the same attribute, generally the resulting attribute value is taken from the last of these features. However, this process is governed by the Ignore Nulls parameter. |
Geometry Accumulation
When Merge Scope is Geometries or Attributes and Geometries, geometries are accumulated.
If the Supplier has geometry whose name the Requestor does not already have, the geometry is added to the Requestor.
If geometries on the Supplier and Requestor feature share the same name (including a blank name) they are deemed conflicted and are handled according to Conflict Resolution.
See Usage Notes > Working with Multiple Geometries above for more information on named geometries.
|
Accumulation Mode |
Select a method for merging geometry:
|
|
Conflict Resolution |
Select a method of resolving same-name collisions:
|
|
Prefix |
When Accumulation Mode is Prefix Supplier, provide a prefix to be applied to the Supplier geometry names. When there are multiple Suppliers for a Requestor , multiple Supplier geometries are merged into the same prefixed geometry name, according to the Supplier Geometry Assembly parameter. |
Advanced
|
Null and Missing Keys |
Select a handling method:
|
||||
|
Preserve Feature Order |
This parameter controls the order in which features exit a transformer. When a transformer has more than one output port, features usually exit one port at a time. At times, it may be useful to keep the order that features arrived in, switching from port to port as necessary. This allows feature order to be preserved, though at a potential cost in processing efficiency. Select a method for feature ordering.
|
Editing Transformer Parameters
Transformer parameters can be set by directly entering values, using expressions, or referencing other elements in the workspace such as attribute values or user parameters. Various editors and context menus are available to assist. To see what is available, click  beside the applicable parameter.
How to Set Parameter Values
Defining Values
There are several ways to define a value for use in a Transformer. The simplest is to simply type in a value or string, which can include functions of various types such as attribute references, math and string functions, and workspace parameters.
Using the Text Editor
The Text Editor provides a convenient way to construct text strings (including regular expressions) from various data sources, such as attributes, parameters, and constants, where the result is used directly inside a parameter.
Using the Arithmetic Editor
The Arithmetic Editor provides a convenient way to construct math expressions from various data sources, such as attributes, parameters, and feature functions, where the result is used directly inside a parameter.
Conditional Values
Set values depending on one or more test conditions that either pass or fail.
Parameter Condition Definition Dialog
Content
Expressions and strings can include a number of functions, characters, parameters, and more.
When setting values - whether entered directly in a parameter or constructed using one of the editors - strings and expressions containing String, Math, Date/Time or FME Feature Functions will have those functions evaluated. Therefore, the names of these functions (in the form @<function_name>) should not be used as literal string values.
Content Types
| These functions manipulate and format strings. | |
|
Special Characters |
A set of control characters is available in the Text Editor. |
| Math functions are available in both editors. | |
| Date/Time Functions | Date and time functions are available in the Text Editor. |
| These operators are available in the Arithmetic Editor. | |
| These return primarily feature-specific values. | |
| FME and workspace-specific parameters may be used. | |
| Creating and Modifying User Parameters | Create your own editable parameters. |
Dialog Options - Tables
Table Tools
Transformers with table-style parameters have additional tools for populating and manipulating values.
|
Row Reordering
|
Enabled once you have clicked on a row item. Choices include:
|
|
Cut, Copy, and Paste
|
Enabled once you have clicked on a row item. Choices include:
Cut, copy, and paste may be used within a transformer, or between transformers. |
|
Filter
|
Start typing a string, and the matrix will only display rows matching those characters. Searches all columns. This only affects the display of attributes within the transformer - it does not alter which attributes are output. |
|
Import
|
Import populates the table with a set of new attributes read from a dataset. Specific application varies between transformers. |
|
Reset/Refresh
|
Generally resets the table to its initial state, and may provide additional options to remove invalid entries. Behavior varies between transformers. |



Note: Not all tools are available in all transformers.
For more information, see Transformer Parameter Menu Options.
Reference
|
Processing Behavior |
|
|
Feature Holding |
Yes |
| Dependencies | None |
| Aliases | ReferenceResolver |
| History |
FME Online Resources
The FME Community and Support Center Knowledge Base have a wealth of information, including active forums with 35,000+ members and thousands of articles.
Search for all results about the FeatureMerger on the FME Community.
Examples may contain information licensed under the Open Government Licence – Vancouver, Open Government Licence - British Columbia, and/or Open Government Licence – Canada.